Hyperconverged Infrastructure (HCI) & Cluster Node Sizing
Patel Galaxify Solutions sizes, supplies, stages, and deploys high-availability Hyperconverged Infrastructure clusters. Consolidate enterprise compute, software-defined NVMe storage, and virtualization into unified, linearly scalable x86 ReadyNodes powered by VMware vSAN, Nutanix, and open ecosystems.
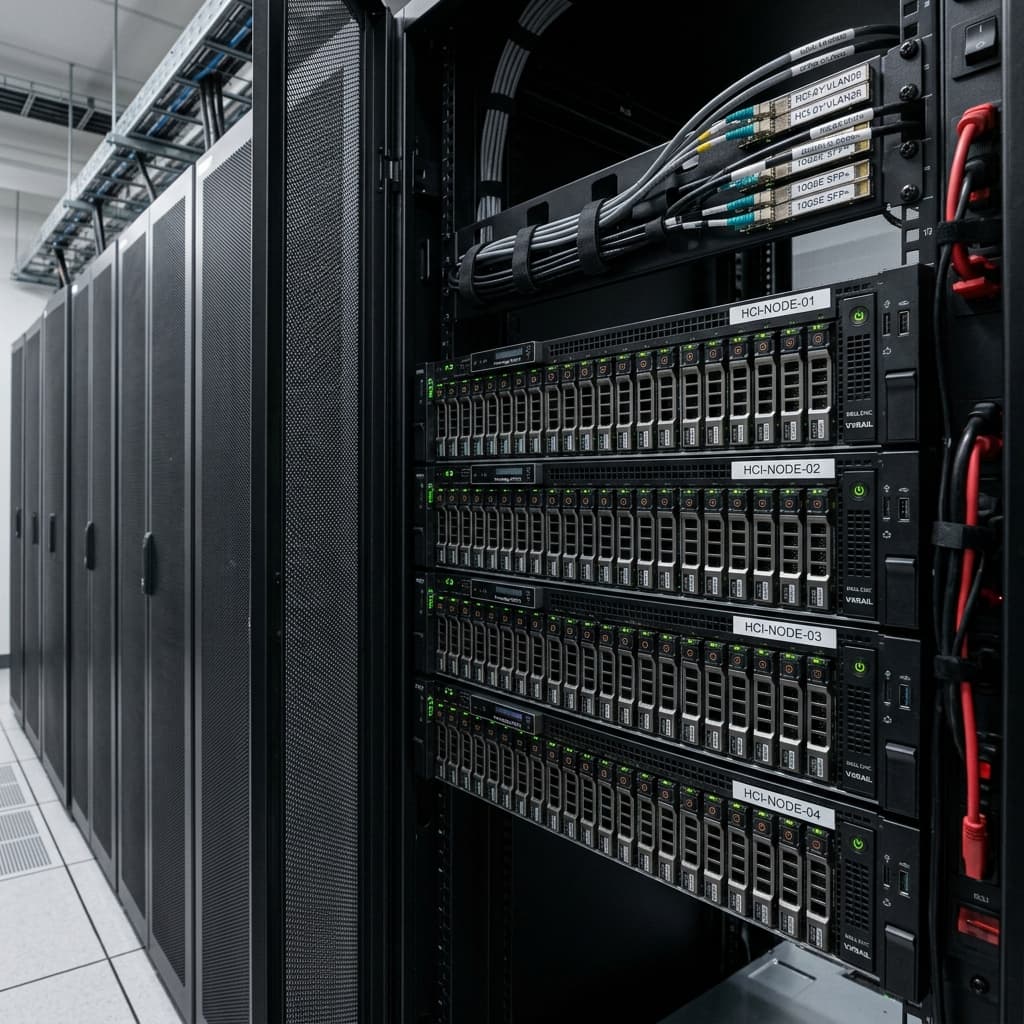
4-NODE ENTERPRISE HCI CLUSTER
N+1 failure domain, dual 25GbE RDMA backplane & NVMe tier
Why Enterprises Transition from Three-Tier to HCI
Traditional multi-vendor arrays demand complex Fibre Channel SAN zoning, proprietary storage controller upgrades, and disjointed maintenance renewals.
Silo Elimination & Consolidation
Collapses separate physical SAN/NAS switches, external array controllers, and compute servers into unified high-density x86 building blocks managed through a single software pane.
Predictable Linear Scalability
Scale compute, memory, and high-performance storage in lockstep. Adding an additional node immediately expands both IOPS and aggregate raw capacity without forklift upgrades.
N+1 & N+2 Failure Domains
Distributed software-defined storage maintains data parity across discrete physical chassis. Complete host loss or drive failures trigger automated background re-mirroring with zero data loss.
Ultra-Low NVMe-oF & RoCE Latency
Eliminates legacy Fibre Channel HBA overhead by leveraging direct-attached NVMe storage caddies interlinked via dual 25GbE RDMA (RoCE v2) east-west fabric networks.
Enterprise HCI Node Platforms Sized to Your Workload
We source and configure 100% genuine Tier-1 enterprise HCI ReadyNodes from Dell Technologies, Hewlett Packard Enterprise (HPE), and Lenovo.
All-Flash NVMe High-Performance HCI
Engineered for high-concurrency databases, enterprise ERP engines (SAP HANA, Oracle), and high-density Virtual Desktop Infrastructure (VDI). Employs ultra-fast NVMe write cache coupled with enterprise TLC NVMe capacity drives.
IDEAL WORKLOADS:
Core data center virtualization, mission-critical SQL/Oracle transactional clusters, and intensive VDI environments.
NODE SPECIFICATIONS & INTERCONNECTS:
- Dual Intel Xeon Scalable (4th/5th Gen) or AMD EPYC 9004 series processors (up to 128 cores/node)
- Dedicated high-endurance NVMe (DWPD ≥ 3) write-caching tier with zero-penalty deduplication
- Dual-port or quad-port 25GbE SFP28 RDMA interfaces dedicated to cluster storage heartbeats
- Support for VMware vSAN ESA (Express Storage Architecture) or Nutanix AOS All-Flash
REPRESENTATIVE HARDWARE:
Dell PowerEdge R760 vSAN ReadyNode, HPE ProLiant DL380 Gen11 Nutanix Node, Lenovo ThinkAgile VX650
Hybrid Tiered Enterprise HCI
Balances ultra-fast flash caching with cost-effective SAS/SATA high-capacity storage tiers. Frequently accessed hot blocks reside on flash, while historical snapshots and cool data demote to magnetic spinning disk.
IDEAL WORKLOADS:
Branch office consolidation, mid-market virtualization, staging environments, and regional distribution hub IT.
NODE SPECIFICATIONS & INTERCONNECTS:
- Dual mid-core enterprise processors optimized for cost-effective hypervisor per-core licensing
- Mixed storage backplane combining enterprise SAS SSD caching with 7.2K SAS HDDs
- Redundant 10G/25G networking maintaining separate management, vMotion, and storage traffic
- Certified for VMware vSAN, Nutanix Cloud Platform, and open-source Proxmox VE / Ceph clusters
REPRESENTATIVE HARDWARE:
Dell PowerEdge R660/R760 Hybrid ReadyNodes, HPE ProLiant DL380 Gen11 Hybrid, Lenovo ThinkAgile HX3330
2U 4-Node Multi-Node High-Density HCI
Packs four independent hot-pluggable dual-socket server nodes into a single 2U chassis with shared high-efficiency titanium power supplies. Maximizes computing density in colocation cages where rack space carries high premiums.
IDEAL WORKLOADS:
Colocation edge data centers, dense testing/QA clouds, microservices clusters, and compute-dense virtualized fleets.
NODE SPECIFICATIONS & INTERCONNECTS:
- Four independent hot-swappable server sleds in a single 2U chassis
- Shared redundant 2000W–3000W Titanium-efficiency power supply bays with active load balancing
- Independent out-of-band management controller (iDRAC/iLO) per node sled
- Integrated front drive backplane allocating 6× 2.5" hot-swap NVMe/SAS drives to each discrete sled
REPRESENTATIVE HARDWARE:
Dell PowerEdge C6620, Supermicro BigTwin Multi-Node, HPE Apollo High-Density Systems
Edge & Remote Office (ROBO) 2-Node HCI
Cost-optimized two-node high-availability clusters utilizing an external cloud or witness server. Designed to maintain continuous local application availability at remote manufacturing plants or branch logistics centers without requiring local SANs.
IDEAL WORKLOADS:
Manufacturing plant floors, retail logistics warehouses, remote branches, and distributed field facilities.
NODE SPECIFICATIONS & INTERCONNECTS:
- 2-node cluster topology using direct crossover 10G/25G cabling, eliminating external 10G switches
- Remote witness mechanism (cloud witness, micro-witness appliance, or centralized HQ witness)
- Acoustic dampening options and short-depth chassis for wall-mount racks and branch cabinets
- Automatic failover and VM restart within seconds if an edge node suffers physical power failure
REPRESENTATIVE HARDWARE:
Dell PowerEdge R660 Short-Depth ReadyNodes, HPE ProLiant DL360 Gen11 2-Node Clusters
HCI vs. Traditional Three-Tier vs. Dedicated AI/HPC
HCI is not a universal panacea for every enterprise use case. Our architecture desk guides you toward the optimal model based on workload symmetry and scale.
Hyperconverged Infrastructure (HCI)
OPTIMAL FOR:
General virtualization, mixed corporate workloads, VDI, branch offices, rapid linear scaling.
LIMITATIONS & CONSTRAINTS:
Storage and compute scale together; extreme unbalanced capacity growth (e.g., 500TB storage for only 4 CPUs) can become commercially inefficient.
Traditional 3-Tier (Compute + SAN/NAS)
OPTIMAL FOR:
Massive scale-up relational databases (Oracle RAC, SAP HANA), massive unstructured data lakes (multi-PB archives).
LIMITATIONS & CONSTRAINTS:
Operational complexity: requires managing dedicated Fibre Channel fabrics, zoning, external LUN masking, and disparate support contracts.
Dedicated AI/HPC GPU Clusters
OPTIMAL FOR:
Distributed LLM training, high-throughput model inferencing, molecular modeling, parallel CFD simulations.
LIMITATIONS & CONSTRAINTS:
Hypervisor virtualization introduces memory and PCIe communication overhead. Demands bare-metal scheduling and non-blocking InfiniBand fabrics.
Information Needed for an Accurate HCI Sizing BOM
To provide an exact, competitively priced Bill of Materials (BOM) with manufacturer warranty verification, our engineering desk reviews these 6 parameters.
Workload Inventory & IOPS Baseline
Consolidation Ratio & Core Allocation
Memory Sizing & N+1 Headroom
Raw to Usable Storage & Erasure Coding
Network Backplane & RDMA Fabric
Software Ecosystem & Licensing Match
Hyperconverged Infrastructure (HCI) FAQ
Guidance for infrastructure architects, CIOs, and data center procurement teams.
What is the minimum number of nodes required to deploy an enterprise HCI cluster?
How does Patel Galaxify Solutions distinguish between vSAN ReadyNodes and proprietary appliances?
Can we mix different server generations or drive sizes within the same HCI cluster?
How do you handle workload migration from legacy SAN/servers to the new HCI cluster?
What Annual Maintenance Contracts (AMC) and on-site hardware support are available?
Complementary Enterprise Solutions
HCI clusters operate synergistically alongside our enterprise storage, backup repositories, and networking fabrics.
Enterprise Storage Solutions
Dedicated SAN, NAS, and All-Flash NVMe primary arrays for petabyte-scale data lakes.
Enterprise Servers & Compute
1U–4U rack servers, multi-socket scale-up database servers, and general x86 infrastructure.
Backup & Disaster Recovery
Hardened immutable backup targets, ransomware-isolated repositories, and DR orchestration.
Enterprise Networking Fabric
High-speed 25G/100G spine-leaf switching fabric engineered for lossless HCI clustering.
Consolidate Your Data Center on Enterprise ReadyNodes
Connect with our certified infrastructure architects to calculate your cluster node requirements, design an N+1 failure domain, and receive competitive BOM pricing with Pan-India delivery.