Specialized Infrastructure for Data Centers & Supercomputing Halls
Patel Galaxify Solutions engineers, stages, and deploys high-density compute across India: AI/HPC GPU supercomputing nodes, non-blocking 400G InfiniBand/RoCE fabrics, parallel NVMe storage arrays, and turnkey rack containment facilities.
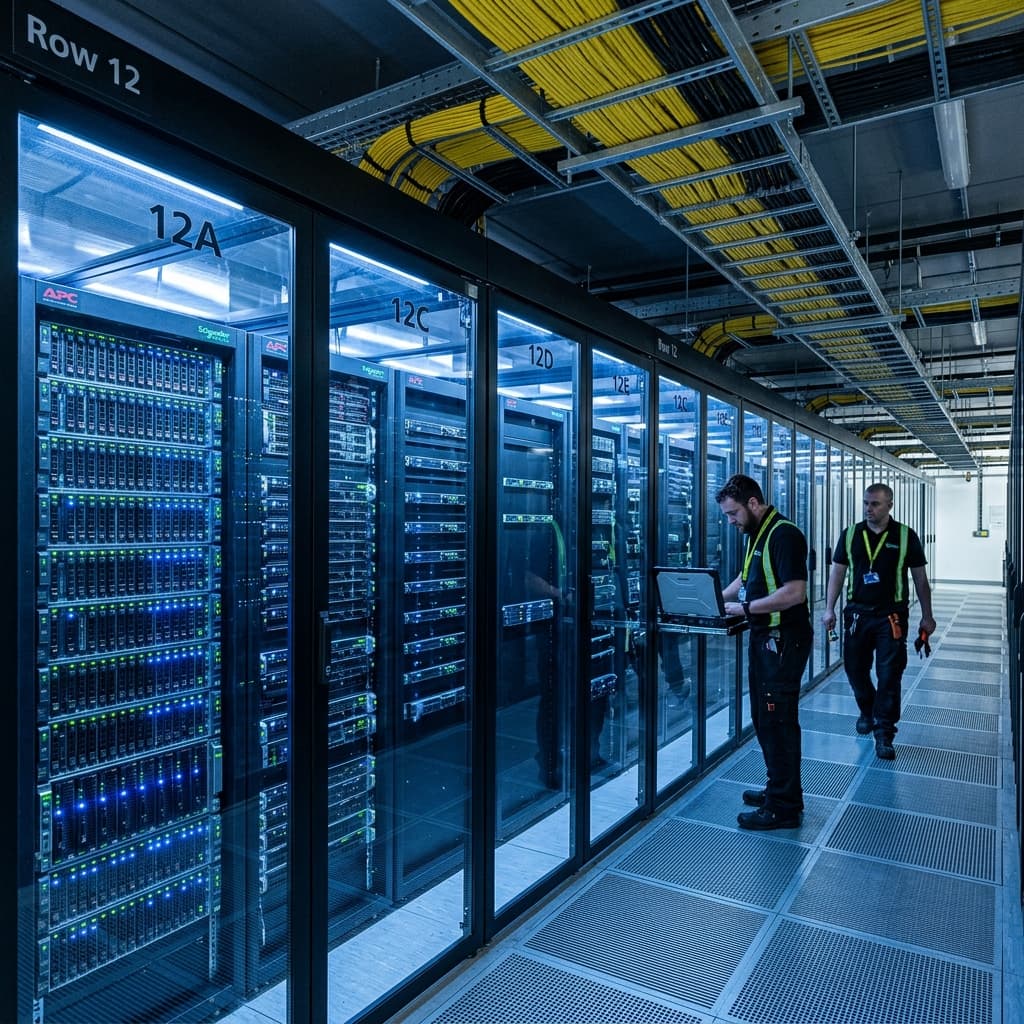
HIGH-DENSITY DATA CENTER ROW
Cold-aisle containment, 400G fabrics & GPU supercomputing
Overcoming Density, Thermal & Throughput Barriers
Scale-out AI training and parallel research simulations push server power density, fabric latency, and storage bandwidth beyond traditional enterprise thresholds.
Extreme Power Density & Thermal Dissipation Limits
Modern AI GPU clusters draw 30kW to 100kW+ per rack, requiring specialized high-load server cabinets, intelligent 3-phase PDUs, and cold-aisle containment to eliminate hot spots and prevent thermal throttling.
Interconnect Bandwidth & East-West Latency Bottlenecks
Multi-node distributed deep learning workloads (LLM training, molecular dynamics) saturate conventional 10G/25G networks, necessitating non-blocking 400Gbps NDR InfiniBand or 400G RoCE v2 fabrics with sub-microsecond latency.
I/O Starvation on Deep Learning & Simulation Pipelines
Massive GPU clusters processing millions of checkpoints and training samples experience severe idle GPU cycles if backend storage cannot sustain hundreds of gigabytes per second in parallel All-Flash NVMe throughput.
Colocation Cage Space & Power Utilization Efficiency
Escalating per-rack colocation and power pricing demands maximum compute density per rack unit, necessitating 2U 4-node multi-sled architectures and modular GPU compute sleds over conventional single-node servers.
High-Density Infrastructure for Research & Cloud
Four specialized infrastructure pillars delivering sustained computational density, sub-microsecond interconnects, and scalable parallel I/O.
Turnkey Server Rack Infrastructure & Thermal Containment
Turnkey colocation and server hall physical infrastructure: high-capacity heavy-duty racks (1500kg+ dynamic load rating), intelligent 3-phase metered/switched PDUs, and modular aisle containment.
Key Technical Specifications:
Representative OEM Hardware:
Vertiv VR Racks / Geist PDUs, Schneider Electric APC NetShelter SX, Eaton RS Enclosures
AI & Scientific GPU Supercomputing Nodes
Enterprise GPU compute nodes purpose-built for large language model (LLM) training, physics simulation, genomics, and computational fluid dynamics (CFD).
Key Technical Specifications:
Representative OEM Hardware:
Dell PowerEdge XE9680, Supermicro GPU SuperServer SYS-821GE, HPE Cray / Apollo XD6500
400G Non-Blocking InfiniBand & Spine-Leaf Network Fabrics
Ultra-high-throughput, ultra-low-latency spine-leaf network switching fabrics engineered for distributed GPU cluster scaling and parallel storage communication.
Key Technical Specifications:
Representative OEM Hardware:
NVIDIA Quantum-2 QM9700 Series, Arista 7060X / 7050X Series, Cisco Nexus 9300 / 9500
Parallel All-Flash NVMe Storage Clusters
High-bandwidth parallel storage architecture engineered to feed GPU compute clusters without I/O starvation, utilizing NVMe-oF, Lustre, IBM Spectrum Scale (GPFS), or Ceph.
Key Technical Specifications:
Representative OEM Hardware:
Dell PowerScale / PowerStore NVMe, NetApp EF-Series / AFF A-Series, VAST Data Universal Storage
Facility Assessment to Turnkey Production
A comprehensive 6-stage lifecycle ensuring high-density computing clusters meet thermal specifications, fabric reliability, and mission-critical SLAs.
Facility Constraints & Workload Dimensioning Audit
We audit your colocation hall power envelopes (kW per rack), floor loading limits, aisle cooling airflow CFM, and compute requirements (CUDA cores, memory bandwidth, network fabric).
Cluster Architecture Formulation & Thermal Modeling
Our data center solutions architects design non-blocking spine-leaf network topologies, calculate PDU phase balancing, and model thermal heat loads across rack rows.
Authorized Distribution Sourcing & Serialized Tracking
Procuring 100% genuine Tier-1 enterprise hardware directly from authorized national distribution channels with official GST invoices and registered OEM warranties.
Staging, InfiniBand Burn-In & Fabric Validation
Unboxing, rail installation, updating switch and server firmware to validated enterprise releases, configuring RoCE/InfiniBand fabrics, and running 72-hour stress testing prior to dispatch.
Insured Transit & Direct Colocation Delivery
Coordinating insured freight delivery with specialized shock-mounted packaging directly into colocation cages or research data centers across India with valid e-way bills.
Mission-Critical AMC SLAs & Dedicated Buffer Spares
Providing comprehensive Annual Maintenance Contracts (AMC) backed by localized buffer spares in Bengaluru and Jaipur, offering 24×7 4-hour on-site engineering response.
Data Center & Supercomputing FAQs
Clear answers regarding colocation equipment procurement, high-density GPU power distribution, 400G fabrics, and GPUDirect Storage.
Does Patel Galaxify Solutions own data center real estate, or provide the equipment for client facilities?
How do you address the extreme power and cooling requirements of 8-GPU AI supercomputing nodes?
What is the difference between 400G NDR InfiniBand and 400G RoCE v2 for scientific computing clusters?
How does GPUDirect Storage (GDS) accelerate deep learning pipelines compared to standard NFS storage?
What support models and buffer stock guarantees are available for enterprise colocation clusters and research labs?
Enterprise Building Blocks for Data Centers
Connect our data center facility architectures directly with our enterprise solution hardware pillars.
Data Center Infrastructure
Server rack enclosures, intelligent PDUs, aisle thermal containment, and power conditioning.
AI & HPC Infrastructure
GPU supercomputing servers, NVIDIA HGX platforms, and parallel cluster architectures.
Enterprise Networking
400G spine-leaf switching, InfiniBand fabrics, RoCE v2, and high-speed optical transceivers.
Enterprise Storage Solutions
High-throughput All-Flash NVMe parallel storage arrays and GPUDirect-compatible tiers.
Scale Your Colocation & Supercomputing Facility
Collaborate with our data center infrastructure architects to size high-density GPU supercomputers, engineer non-blocking 400G network fabrics, and deploy turnkey aisle containment solutions.